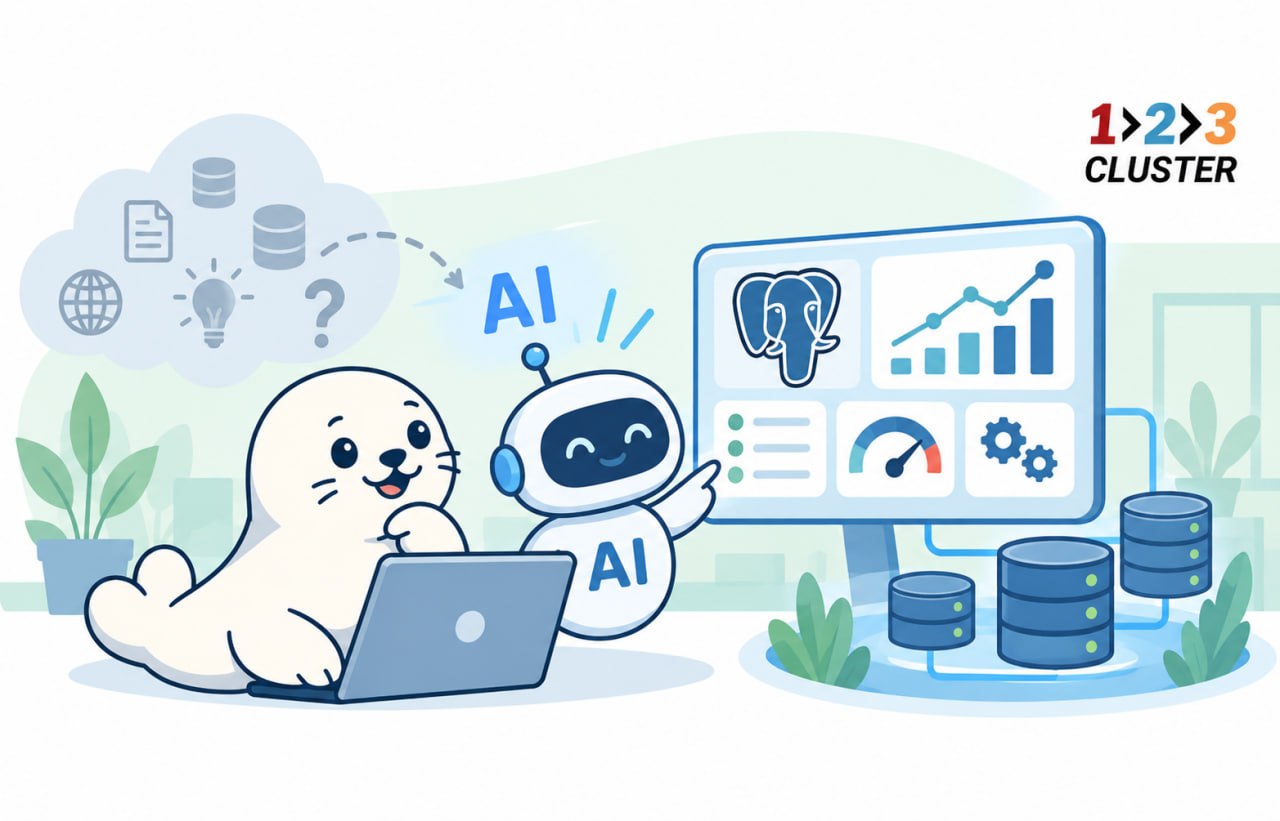
We answer from your data.
• Reads live state before answering. Queries pg_stat_user_tables, pg_stat_replication, and slow query logs in real time. The answer reflects what is happening now.
• Compressed context, not raw logs. The AI receives a structured summary — top queries, error clusters, metric anomalies — not gigabytes of raw log lines.
• Explains before it acts. Every recommendation includes the reasoning. You see which metric triggered the suggestion and what changes.
COST-EFFICIENT AI
The reason most AI database tools get expensive fast: they send raw logs to an external LLM API and charge per token. 123Cluster does not work that way.
SECURITY-FIRST AI
Infrastructure data — query patterns, schema shapes, connection strings — is sensitive. The AI operates inside your deployment, not in a shared SaaS layer.
EXAMPLES
you: What's killing query performance since the deploy at 14:30?
AI: Top offender — sequential scan on orders.customer_id (rank #1 by total time).
Appeared 4,847 times since 14:30. Avg 2.3s, max 18.4s.
The query fingerprint matches your new reporting endpoint.
There is no index on customer_id — the column was added in today's
migration but the index was not. Table has 47M rows.
Fix: CREATE INDEX CONCURRENTLY idx_orders_customer_id ON orders(customer_id);
Non-blocking. Estimated build time: ~12 minutes at current write rate.
you: autovacuum keeps falling behind on the events table
AI: Confirmed. events has 8.2M dead tuples — 16x over trigger threshold.
Last vacuum: 3 days ago. Current write rate: ~9,400 updates/sec.
Root cause: autovacuum_vacuum_scale_factor = 0.2 (default).
At this write volume the trigger fires once every ~3 days. Should be hourly.
Recommendation (table-level, non-global):
ALTER TABLE events SET (autovacuum_vacuum_scale_factor = 0.01,
autovacuum_vacuum_threshold = 1000);
Apply during low-traffic window. Run VACUUM ANALYZE events after.
ALERT: Replication lag trend — eu-west-2b
AI: Lag has grown from 0.3s to 4.8s over the past 40 minutes.
Rate of growth is accelerating, not plateauing.
Correlation: WAL generation spike at 06:14 UTC (+320% vs 7-day avg).
The replica is not I/O bound — walreceiver is the bottleneck.
Most likely cause: bulk write job started at 06:10.
At current rate, lag will exceed 30s in ~18 minutes.
Options: set synchronous_commit=local for the session,
or redirect reads to eu-west-2a during the write window.
Connect a cluster and ask the first question.
No setup. The AI is live the moment your cluster is connected.


Automate deployment, scaling, and maintenance of your database clusters to ensure peak performance and reliability.